PrimaLabs ranks #1 on Artificial Analysis for DeepSeek Flash V4 Read the announcement

Application-specific adaptive inference

Own Your Intelligence.

PrimaLabs builds and operates a dedicated inference stack around each workload. Open models, served on sovereign terms, tuned continuously in production. National lab grade adaptive AI, now for enterprise.

WorkloadCoding agents
Generic endpoint · tuned oncePrimaLabs · shaped to the workloadSame traffic

Same traffic in. The stack built for the workload answers faster, and steadier.

Live request traffic arrives in the rhythm of the selected workload, enters a circuit built from the PrimaLabs dot-trace mark, and leaves as a single, steady, optimized stream. Selecting a workload above changes the arriving traffic pattern and the circuit adapts around it.

Why PrimaLabs

#1 for DeepSeek Flash on Artificial Analysis

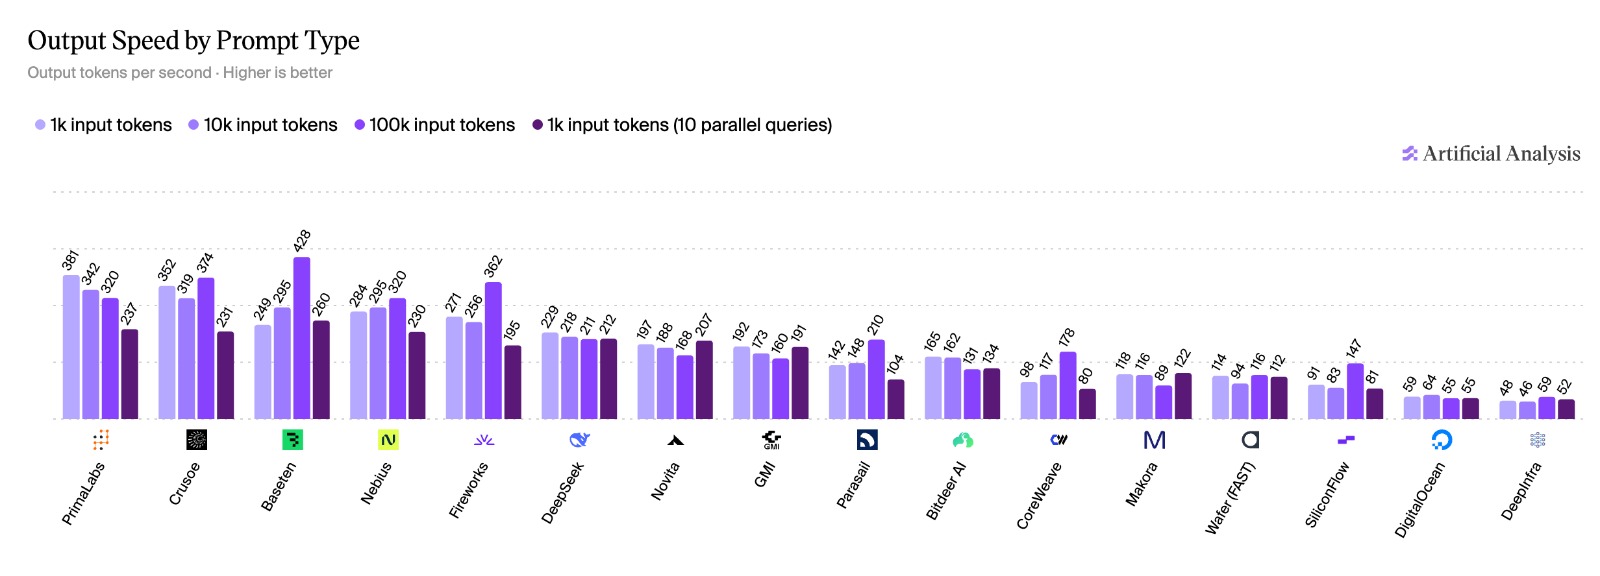
Output speed by prompt type for DeepSeek V4 Flash. PrimaLabs leads across 1k, 10k, 100k, and parallel queries.
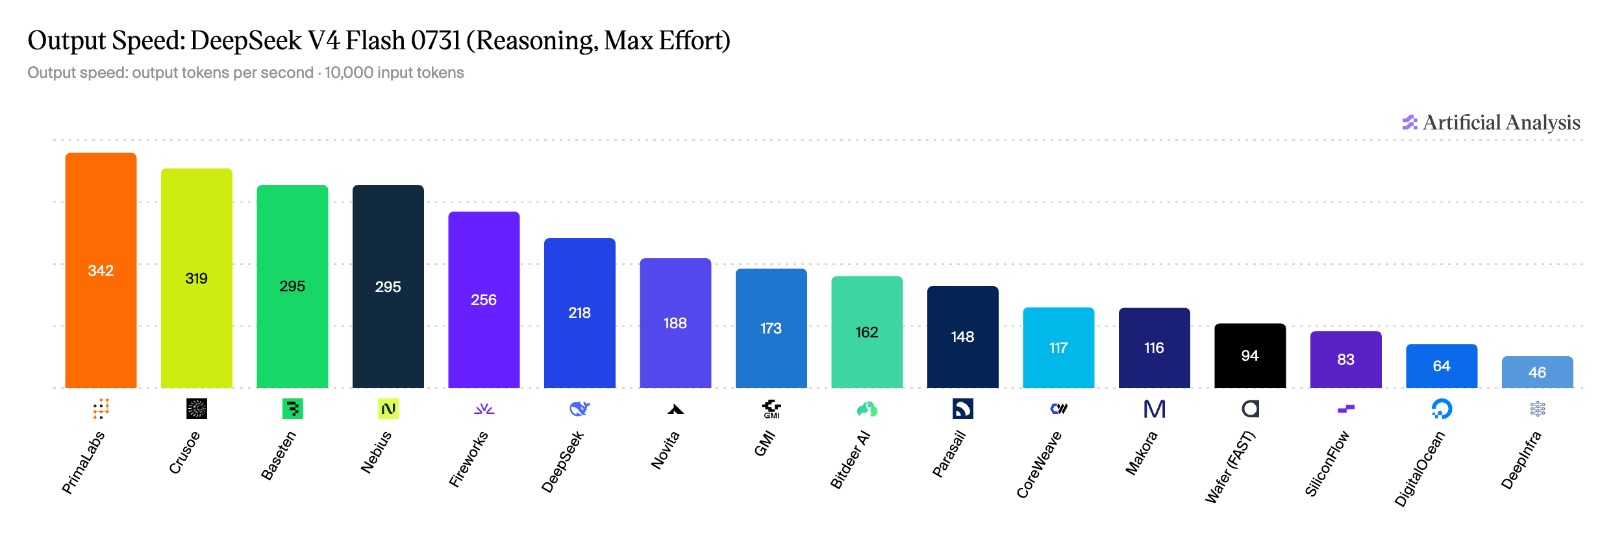
Output speed for DeepSeek V4 Flash 0731 at 10,000 input tokens. PrimaLabs is first at 342 tokens per second.
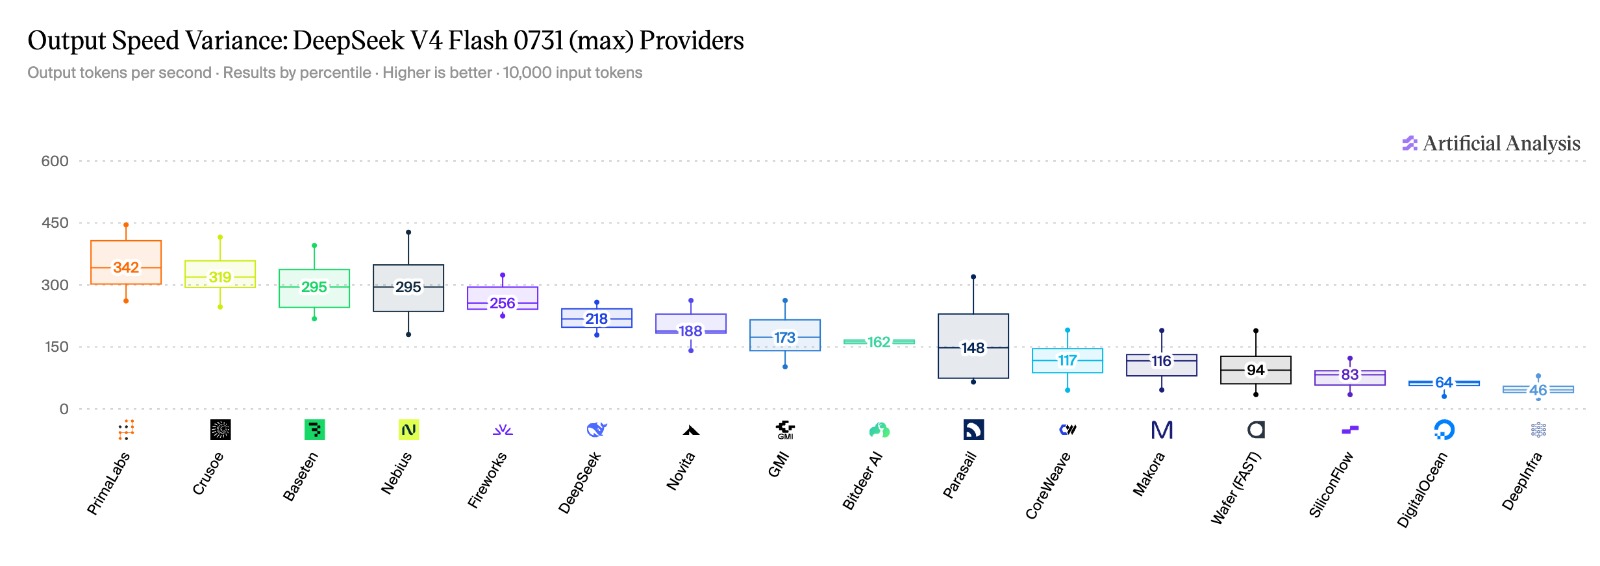
Output speed variance for DeepSeek V4 Flash 0731 providers. PrimaLabs is first at 342 tokens per second.
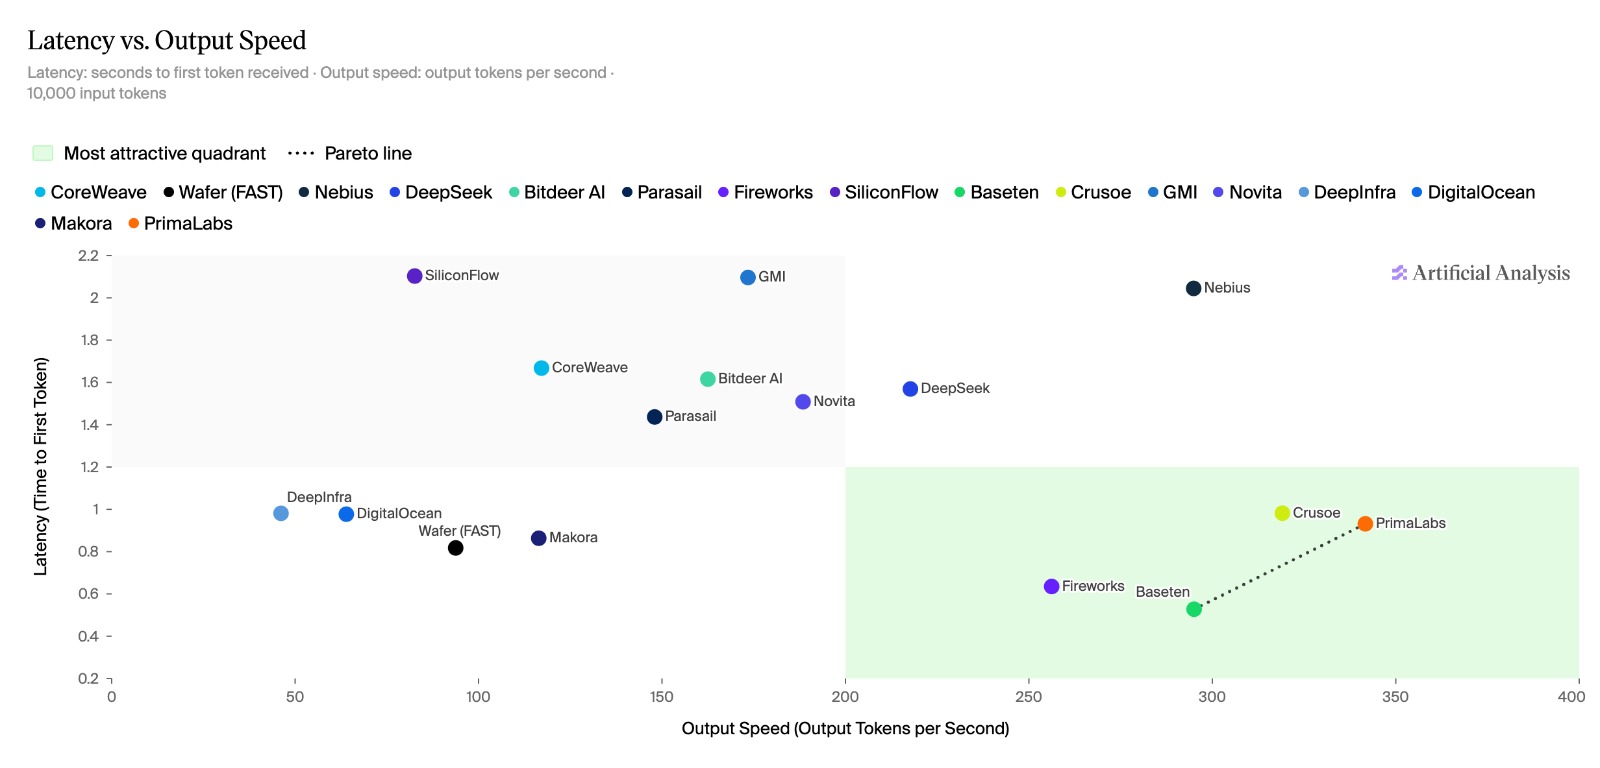
Latency versus output speed for DeepSeek V4 Flash. PrimaLabs sits in the most attractive quadrant.
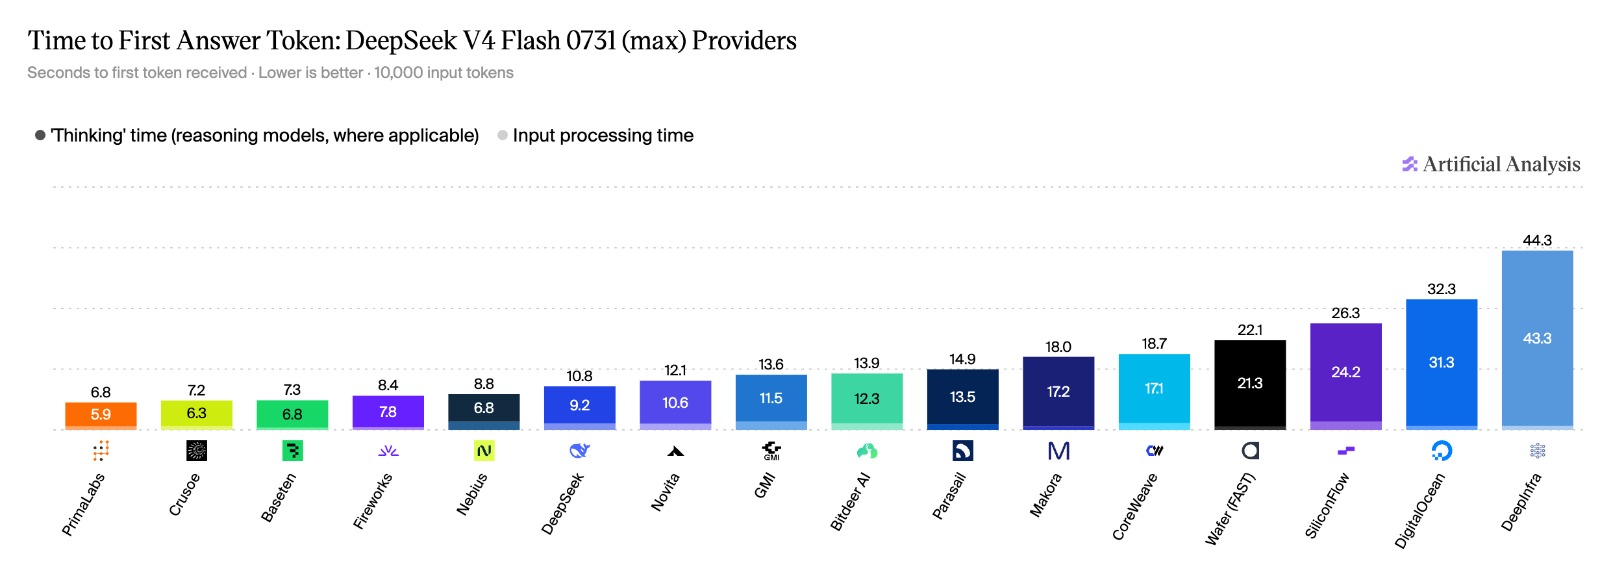
Time to first answer token for DeepSeek V4 Flash 0731. PrimaLabs is fastest at 6.8 seconds.
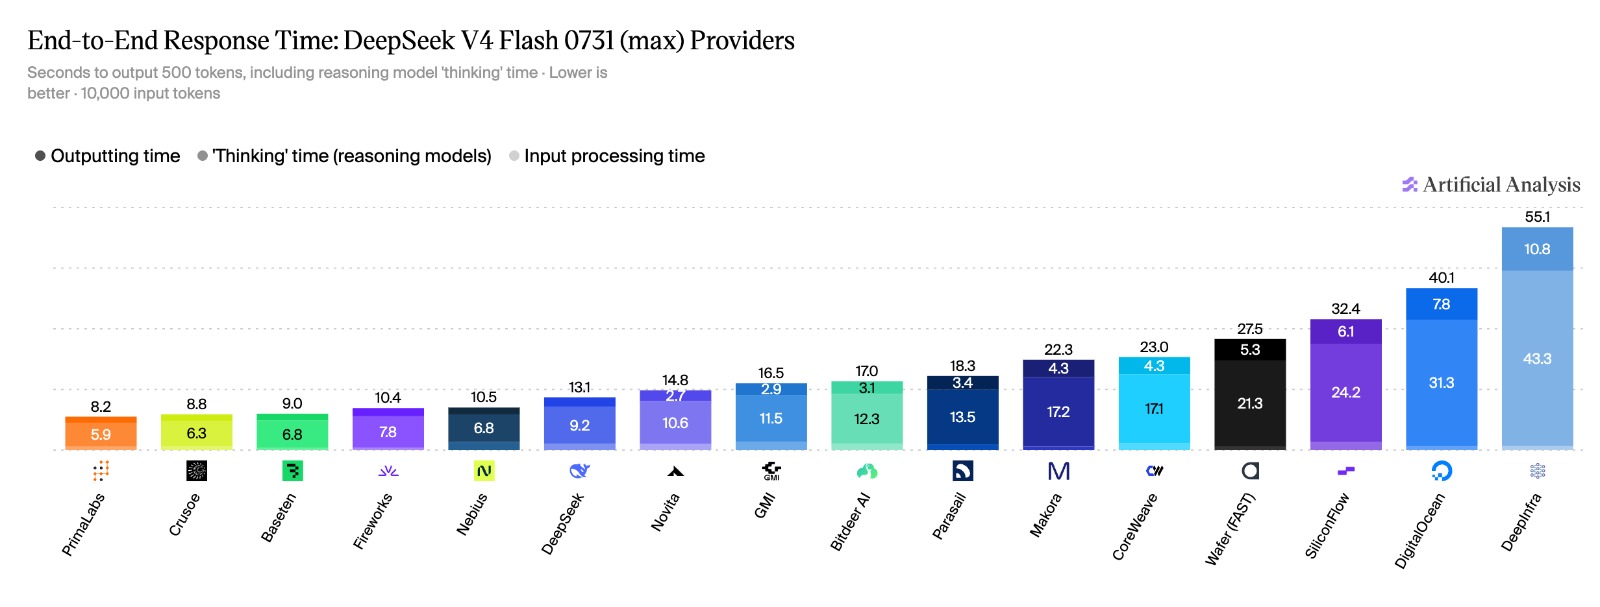
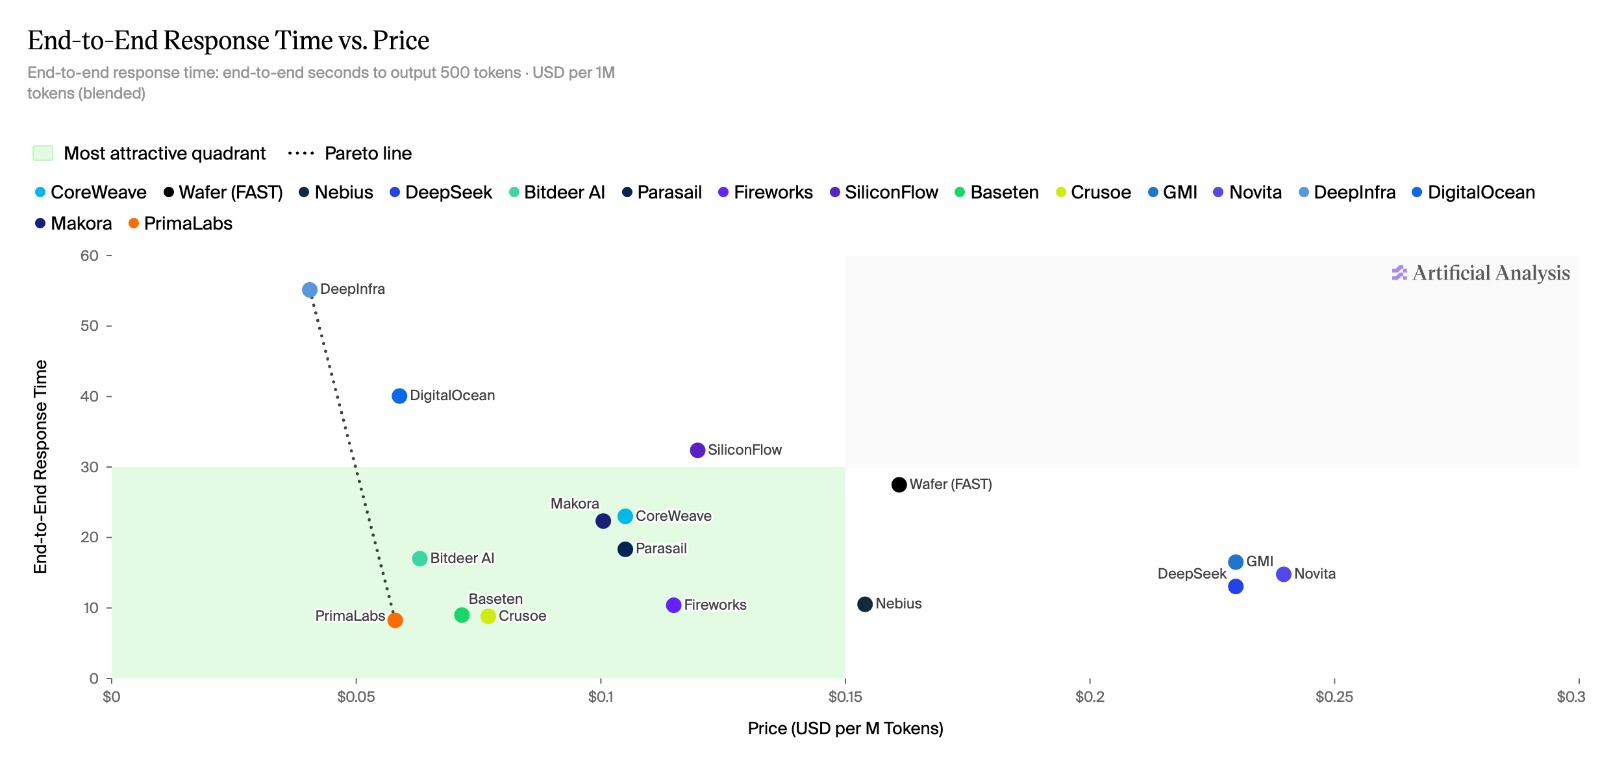
End-to-end response time for DeepSeek V4 Flash 0731 at 10,000 input tokens. PrimaLabs is fastest at 8.2 seconds.
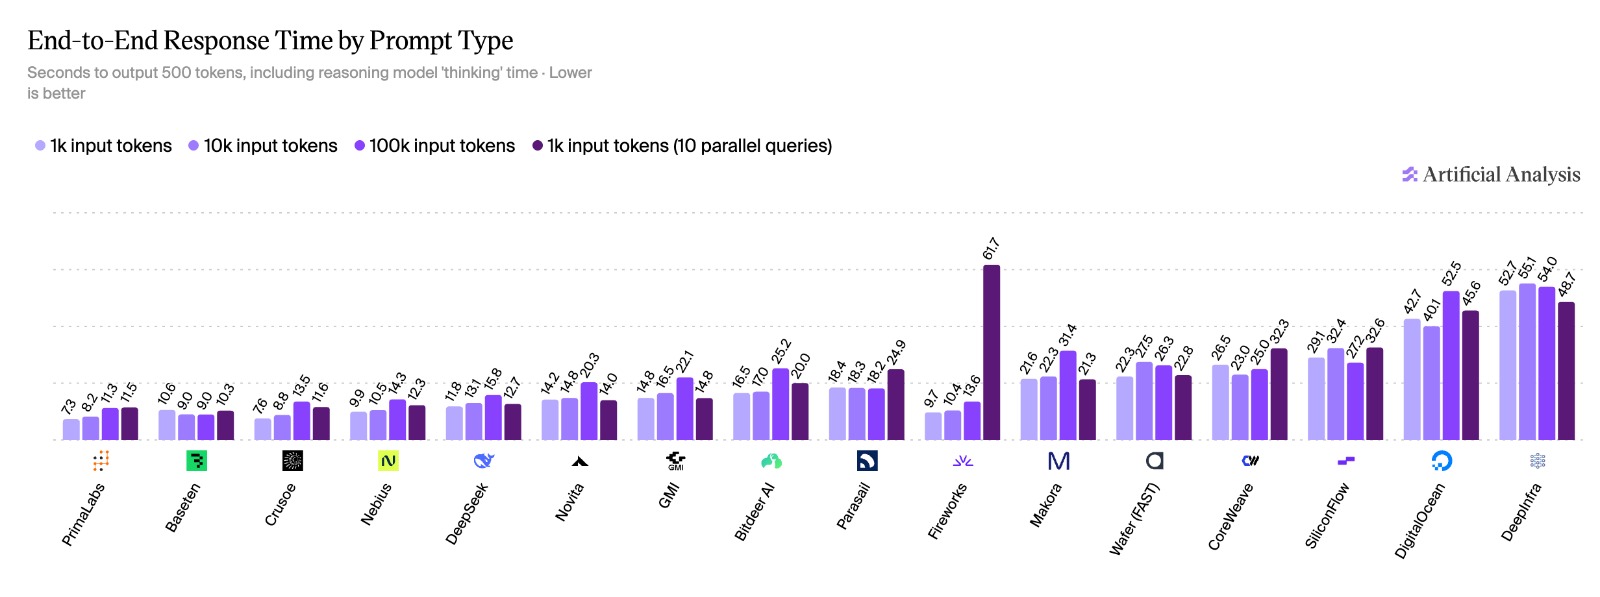
End-to-end response time by prompt type. PrimaLabs is among the lowest across input lengths.
End-to-end response time versus price. PrimaLabs sits in the most attractive quadrant.
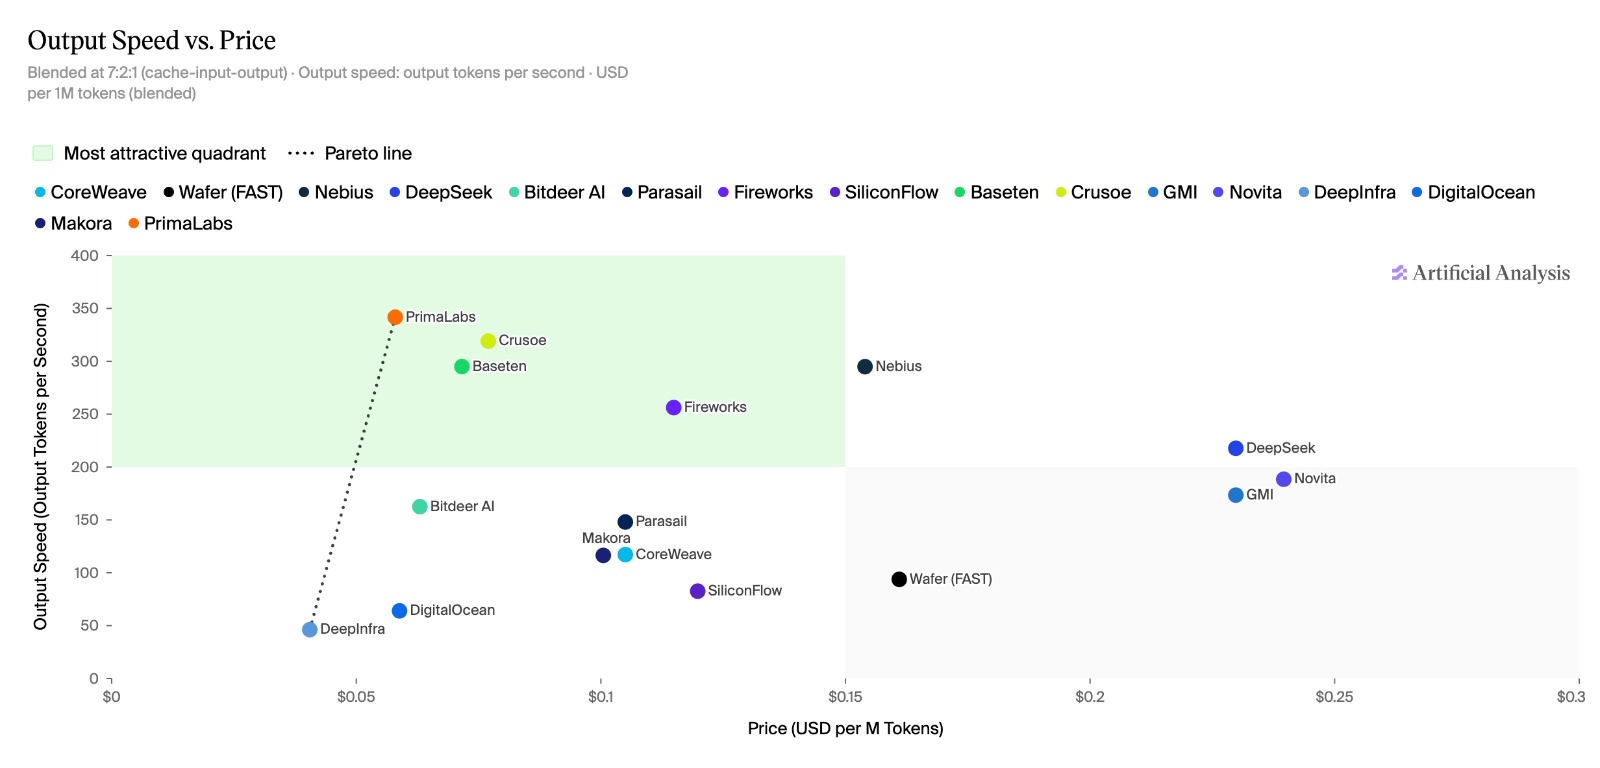
Output speed versus price. PrimaLabs is the fastest provider in the most attractive quadrant.
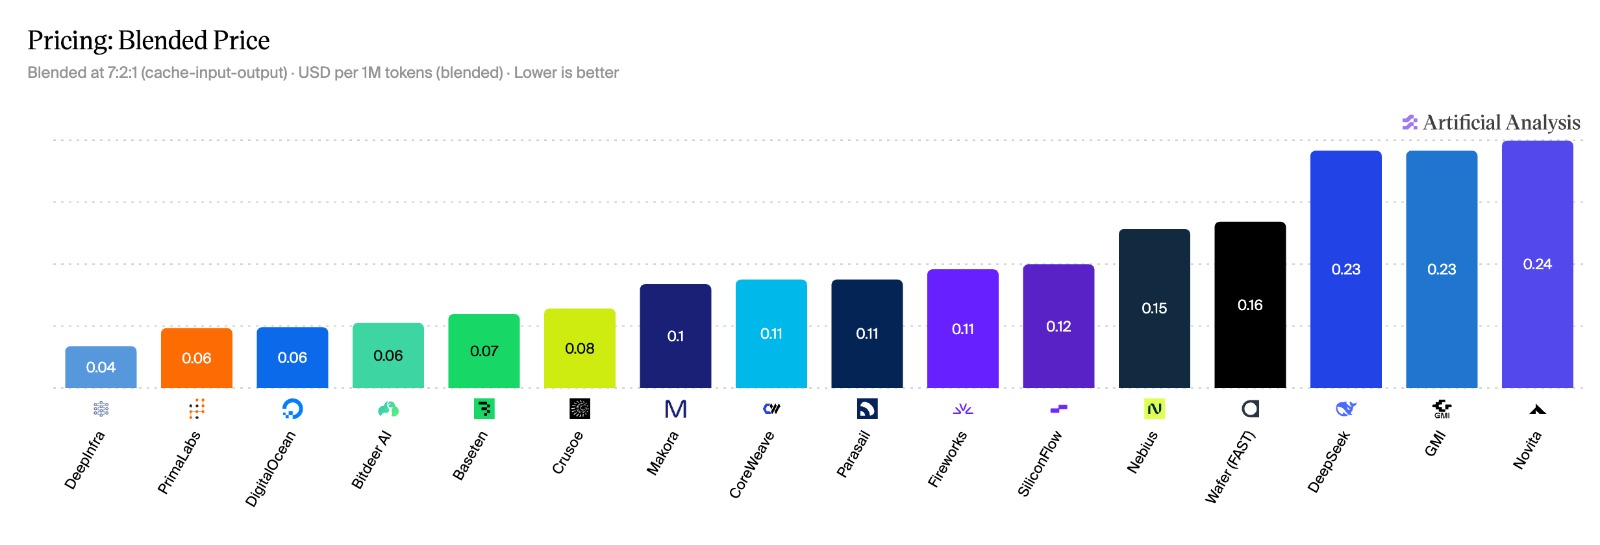
Blended price per million tokens. PrimaLabs is among the lowest at $0.06.
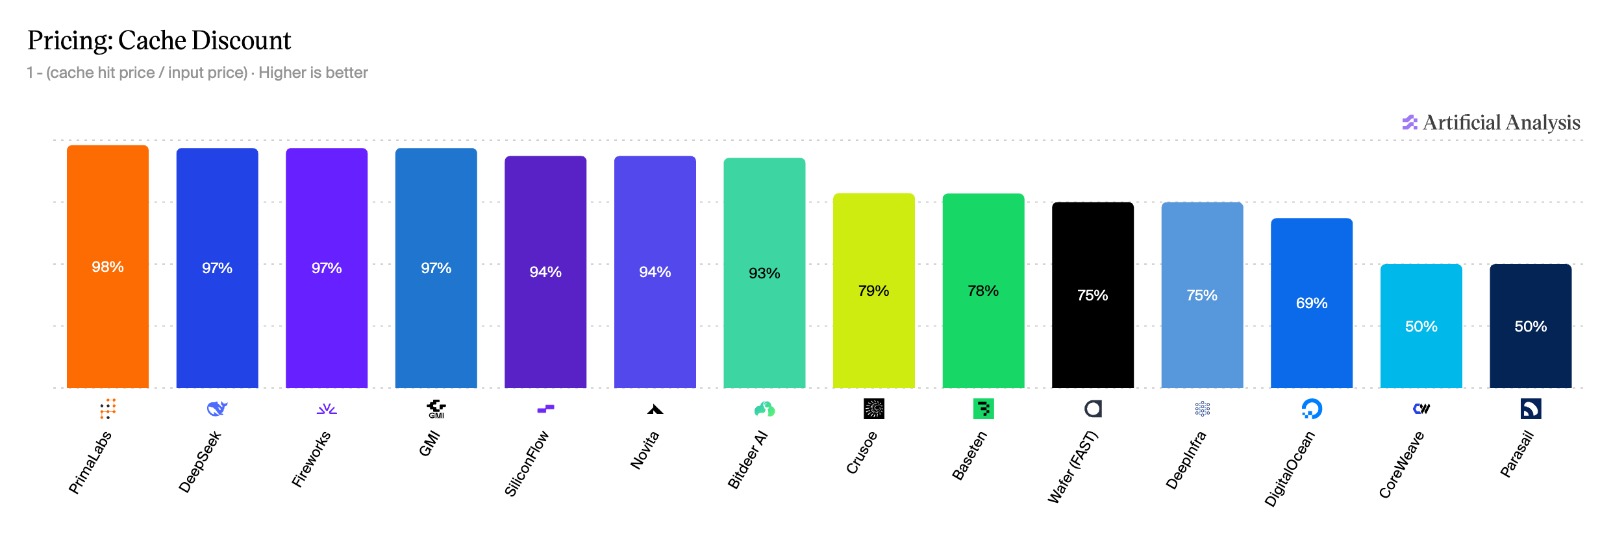
Cache discount by provider. PrimaLabs leads at 98 percent.

Artificial Analysis · DeepSeek V4 Flash

Slide 1 of 11

Why it compounds

The stack learns the workload. Performance compounds. Cost falls as the result.

The stack watches real traffic, learns what this specific workload needs, and ships an improvement only when it measures faster with identical outputs. Generic endpoints are tuned once. This one never stops.

Watch

Reads the live workload in real time, so every decision comes from real traffic, not a synthetic test.

Learn

Carries every win forward. The stack gets faster with use, without ever retaining the data it learns from.

Improve

Ships changes under the SLA, without touching the model or the product. Nothing reaches production on a hunch.

The compounding gap

Generic endpoint

Flat. Tuned once, then frozen

PrimaLabs custom stack

Compounds. The stack learns the workload and improves with volume

Speed on real traffic
VolumeConceptual, not measured dataVertical scale unlabelled by design
Tuning log
04:12Candidate changeShipped
04:31Candidate changeRejected
05:07Candidate changeShipped
05:44Candidate changeRejected
06:20Candidate changeShipped

Nothing reaches production on a hunch.

Built for AI-native workloads

Every workload runs differently. The stack is built for how each one actually runs.

Coding agents

tight loopsinstant responsesinteractive SLA

Agents fire thousands of near-identical requests in tight loops. The stack is built to answer them instantly, so the agent feels native, not throttled.

tight repeating loops

Agentic pipelines

multi-step chainscontext reusehigh cache hit rates

Multi-step agents chain tool calls, plans, and long contexts. The stack keeps every step fast and reuses what the workload repeats, so the whole chain finishes sooner.

chained steps, reused context

AI-native products

interactive latencyburst scaleconsistent p99

When the model is the product, model speed is the product experience. The stack holds interactive latency through bursts and scale.

bursts, held

Proof

One workload. One head-to-head. Numbers in writing.

The workload runs on the current provider and on the PrimaLabs stack, side by side. Throughput, latency, and cost are measured and put in writing before any commitment. Lower cost is what the numbers produce.

Head-to-head evaluation

Measured on the customer workload

ThroughputTBD
LatencyTBD
CostTBD
Measured · In writing
THE TEAM

The discipline of efficient exascale,
applied to enterprise AI inference.

For two decades, the national labs perfected one discipline: extracting maximum useful work from fixed hardware under hard power and thermal limits. That is exactly the problem token cost now faces. PrimaLabs is that discipline applied, by the team behind ORBIT and the largest AI models ever trained on Frontier, the world's first exascale supercomputer.

Built by a team from

Co-founder & CEO
Former Director of AI Programs, Oak Ridge National Laboratory
  • Led ORBIT: 113B-parameter foundation model, 1.6 exaFLOPS sustained on 49,152 GPUs
  • ACM Gordon Bell Prize Finalist, 2024 (ORBIT) and 2025 (ORBIT-2)
  • White House panels and the Tennessee AI Advisory Council
Prasanna Balaprakash
Co-founder, President & COO
Four-time founder, zero-to-one across enterprise SaaS, AI, and healthtech
  • Built and scaled a venture studio incubating early-stage startups
  • Entrepreneur Magazine, Top 25 People in Tech
  • Operator background across GTM, fundraising, and product, from pre-seed to growth
Chaitanya Hiremath

Book a demo

One workload. One comparison. In writing.

Share the workload profile: traffic shape, models in use, latency target, and deployment constraints. PrimaLabs runs the head-to-head and returns the numbers.